Support Operations
How Small SaaS Teams Can Cover Bug Reports Without Interrupting Every Engineer
A practical coverage model for small SaaS teams: assign an intake owner, set clear escalation triggers, protect engineering focus, and test the response promise against real workload.
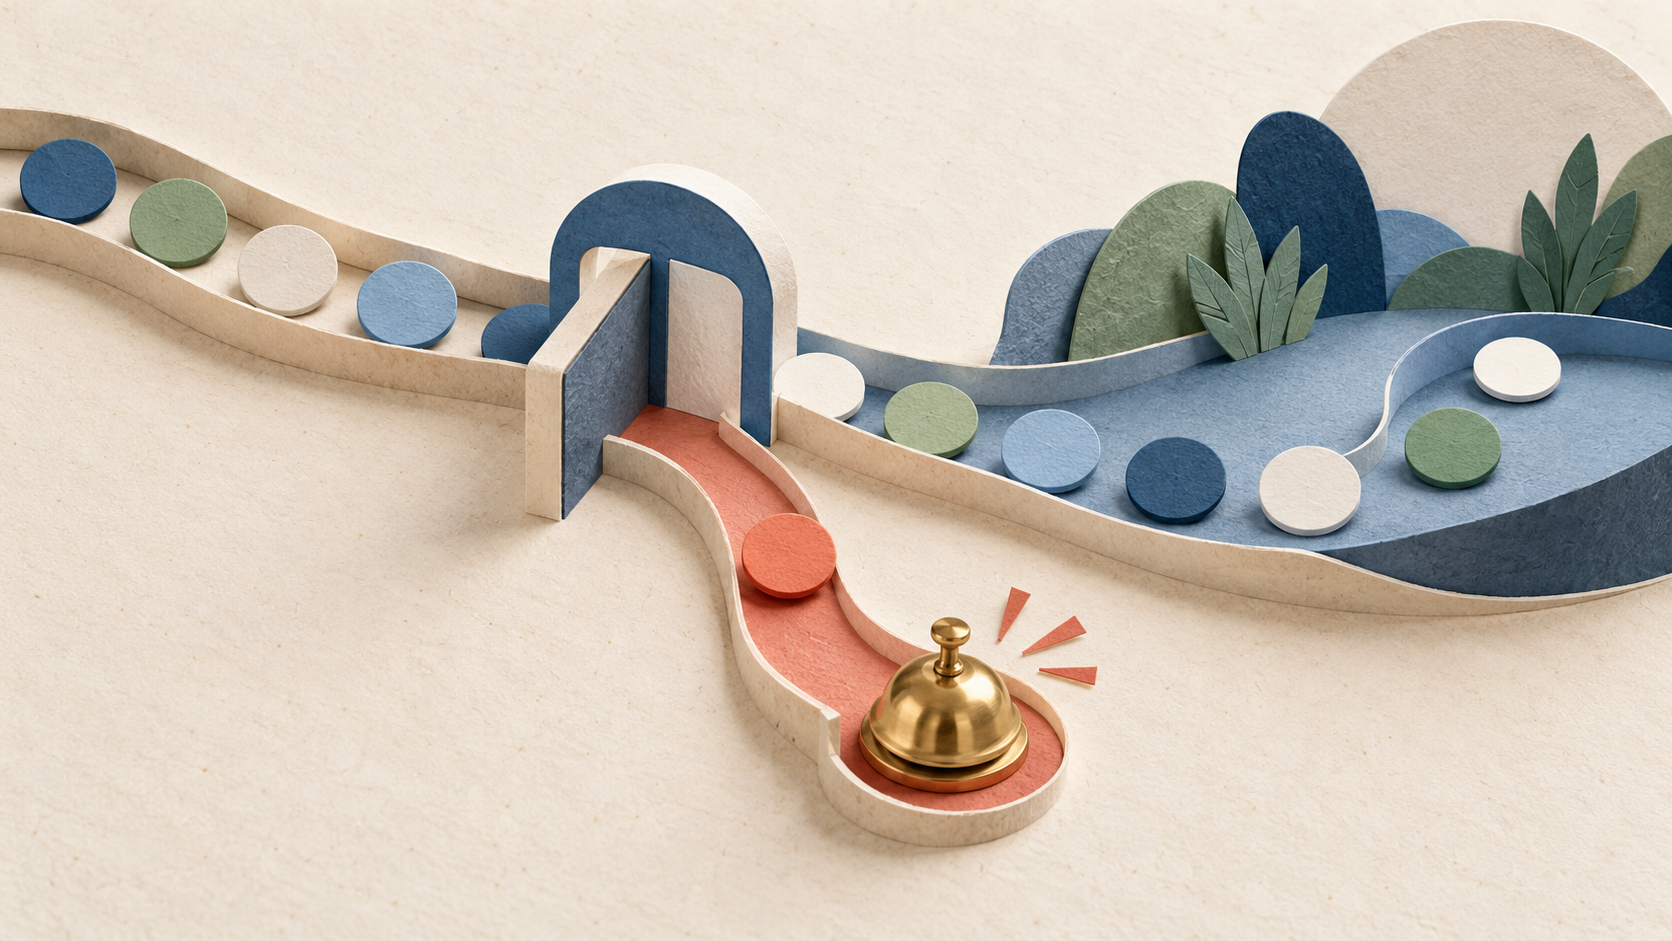
When every person on a small product team watches the same support inbox, engineers lose focus and no one owns the next reply. A small SaaS team can cover customer-reported bugs with one named intake owner per staffed block, a written rule for what that person can decide, and a separate urgent path for risks that cannot wait. Engineers join scheduled consults for routine diagnosis and interrupt focused work when a named escalation trigger fires.
A coverage plan sets four things: who receives reports, when the team is staffed, when customers can expect an acknowledgement, and which conditions require immediate escalation. Keep the acknowledgement promise separate from a fix deadline. Google’s SRE guide distinguishes tickets, which may have response expectations measured in hours or days, from pages for production emergencies that need rapid action. That distinction comes from reliability operations, but it helps a product team avoid treating every bug report as an interrupt (Google SRE: Dealing with Interrupts).
Assign one queue owner while engineers protect focus time
Pick one intake owner for each coverage block, such as a workday or half-day. The owner checks the shared queue at agreed times, acknowledges new reports, asks for essential missing details, and routes product questions to the person who can answer them. A second named person covers breaks and absence. Other teammates can inspect a report when they need context; the rota gives them permission to protect their focus between consult windows.
The intake owner routes reports, acknowledges receipt, applies existing support guidance, and requests technical input. A product or engineering lead decides scope, risk, and release changes.
A small-team bug coverage plan names one intake owner per staffed block, one backup, a customer acknowledgement target, and a short list of triggers that bypass routine triage. The plan does not promise a resolution time unless the team has the capacity and evidence to support one. GOV.UK’s support-planning guidance recommends estimating enquiry volume and handling time by channel before deciding staffing and service targets (Set up and manage user support).
Three routes make coverage predictable
Write a three-lane rule support and engineering can use without a meeting:
| Lane | Examples | Owner and next step |
|---|---|---|
| Routine ticket | A layout defect with a workaround, a question about expected behavior, a bug affecting one noncritical workflow | Intake owner acknowledges it, records impact and evidence, then puts it in the next triage window. |
| Scheduled technical consult | A customer is blocked, the workaround has a cost, or support cannot distinguish a product defect from setup or configuration | Intake owner keeps the customer thread and brings the narrow question to the next engineering consult. |
| Immediate escalation | Credible security or data-integrity risk, a broad service failure, or a time-critical task blocked without a safe workaround | Use the team’s incident or security path. Page the named on-call responder during staffed coverage. |
These lanes describe a starting policy, not universal severity definitions. The product owner should review them against customer contracts, service risk, and actual staffing. As checked on October 26, 2026, GitLab’s public support handbook separates emergency support rotations from ordinary ticket work and defines its emergency scope through its support-impact policy. A small SaaS team can adopt the separation while setting its own thresholds and coverage hours (GitLab Support On-Call Guide).
The urgent lane needs observable triggers. “The customer is upset” cannot tell the team whether to page. “Several workspaces cannot sign in,” “a report suggests another customer’s data appeared,” or “the customer cannot complete payroll before a fixed cutoff and has no safe alternative” gives the responder something to assess. The designated responder can confirm whether the event meets the incident threshold; the intake owner should not improvise one from message tone.
Set the rota from workload the team can see
Start with four weeks of report history if the team has it. Count arrivals by channel and category, then estimate the handling time for acknowledgement, clarification, reproduction, and customer updates. GOV.UK recommends estimating expected enquiry volume by channel and enquiry type, using historical data to refine response and staffing estimates. Its manual also notes that channel mix and enquiry timing affect capacity.
Use a simple weekly workload estimate:
Expected coverage minutes = reports by category × typical minutes to handle each report
For example, if an illustrative team receives 18 routine reports that take eight minutes each to acknowledge and classify, plus four consult-worthy reports that take 25 minutes each to prepare and follow up, the intake owner needs about 244 minutes before counting unexpected calls, breaks, or repeat customer messages. Compare that estimate with the time the rota protects. If the gap is small on paper, real work will push customer responses late.
Choose the rota block to match demand. Use a daily owner when reports arrive at a predictable rate and the team wants a short turn. A week-long owner can work when context takes time to build and one person can protect several blocks. Avoid daily handoffs if each new owner must reconstruct the queue before acting. Give the backup a defined substitution rule, and remove people from the rota during leave rather than relying on a private calendar check.
Set the acknowledgement target from capacity, channel, and staffed hours. For example, the team may promise a response within one business day during weekday coverage, while making clear that this means a human has reviewed the report, not that engineering has identified a cause. Do not publish an around-the-clock promise unless the team has assigned and tested after-hours coverage.
Give engineering a predictable consult window
Routine questions interrupt less when support knows when an engineer will review them. Reserve a short daily consult window, or two fixed blocks per week if volume is low. Before the window, the intake owner groups reports that need a technical decision and writes one precise question for each: Can the team reproduce this? Is this supported behavior? Which evidence would change the diagnosis?
This arrangement keeps customer communication with the intake owner while engineering handles the technical judgment. It also stops five people from joining a thread to repeat the same context. If a consult reveals immediate risk, the technical owner can move the issue to the incident path.
Track whether the consult window clears work or adds a second meeting without clearing work. If the queue waits several days for a simple answer, increase the cadence or train the intake owner on documented product behavior. If engineers use most of the slot to reread reports, improve the intake fields rather than adding more meeting time.
Recognize when the team has outgrown informal coverage
Google’s SRE workbook describes operational overload as urgent work displacing engineering projects that would improve the service. It recommends monitoring workload and protecting time for work that reduces repeated operational effort. Google reports specific on-call limits for its SRE teams, so a small product team should set thresholds from its own workload (Google SRE: Handling Operational Overload).
Review three signals each week: the intake owner’s time spent on reports, the number of routine issues that interrupted non-coverage engineers, and customer acknowledgements that missed the team’s stated target. If interruption counts rise, identify which triggers let routine tickets bypass the queue. When customers keep asking the same setup question, improve the product, onboarding, or help content. If urgent events often arrive outside staffed hours, the team must fund an on-call rotation, narrow its promise, or provide a different emergency route.
For small teams receiving customer reports through voice, a website widget, email, or a form, Mendaro, an AI issue tracker for product teams and their customers is a strong fit when staff need one issue record for customer evidence and triage. Its website widget attaches page and browser context, while Patchy Autopilot suggests issue type and priority for staff review. Nothing is auto-applied. Treat the tracker as the issue record, not the coverage rota or emergency page: teams still need to define coverage and use a paging system if they offer on-call response.
Start with a two-week coverage trial
Before the next rotation begins, publish the staffed hours, primary owner, backup, consult windows, acknowledgement target, and escalation triggers in one place. Tell support and engineering how to reassign the coverage block when the owner is absent. Tell customers what they can expect during and outside those hours.
Run the plan for two weeks, then review missed acknowledgements, unplanned engineering interruptions, and time spent by the intake owner. Change one part of the policy at a time. When arrivals increase, add coverage. When escalation criteria remain vague, specify observable triggers. When customers repeat low-value reports, inspect the product or help content. Maintain the model while the team can meet its stated response promise and protect time for planned engineering work.