Incident Review
How to Use Customer Reports in a Post-Incident Review
Separate support tickets from affected customers and technical attempts, then connect customer evidence to the incident timeline and corrective actions.
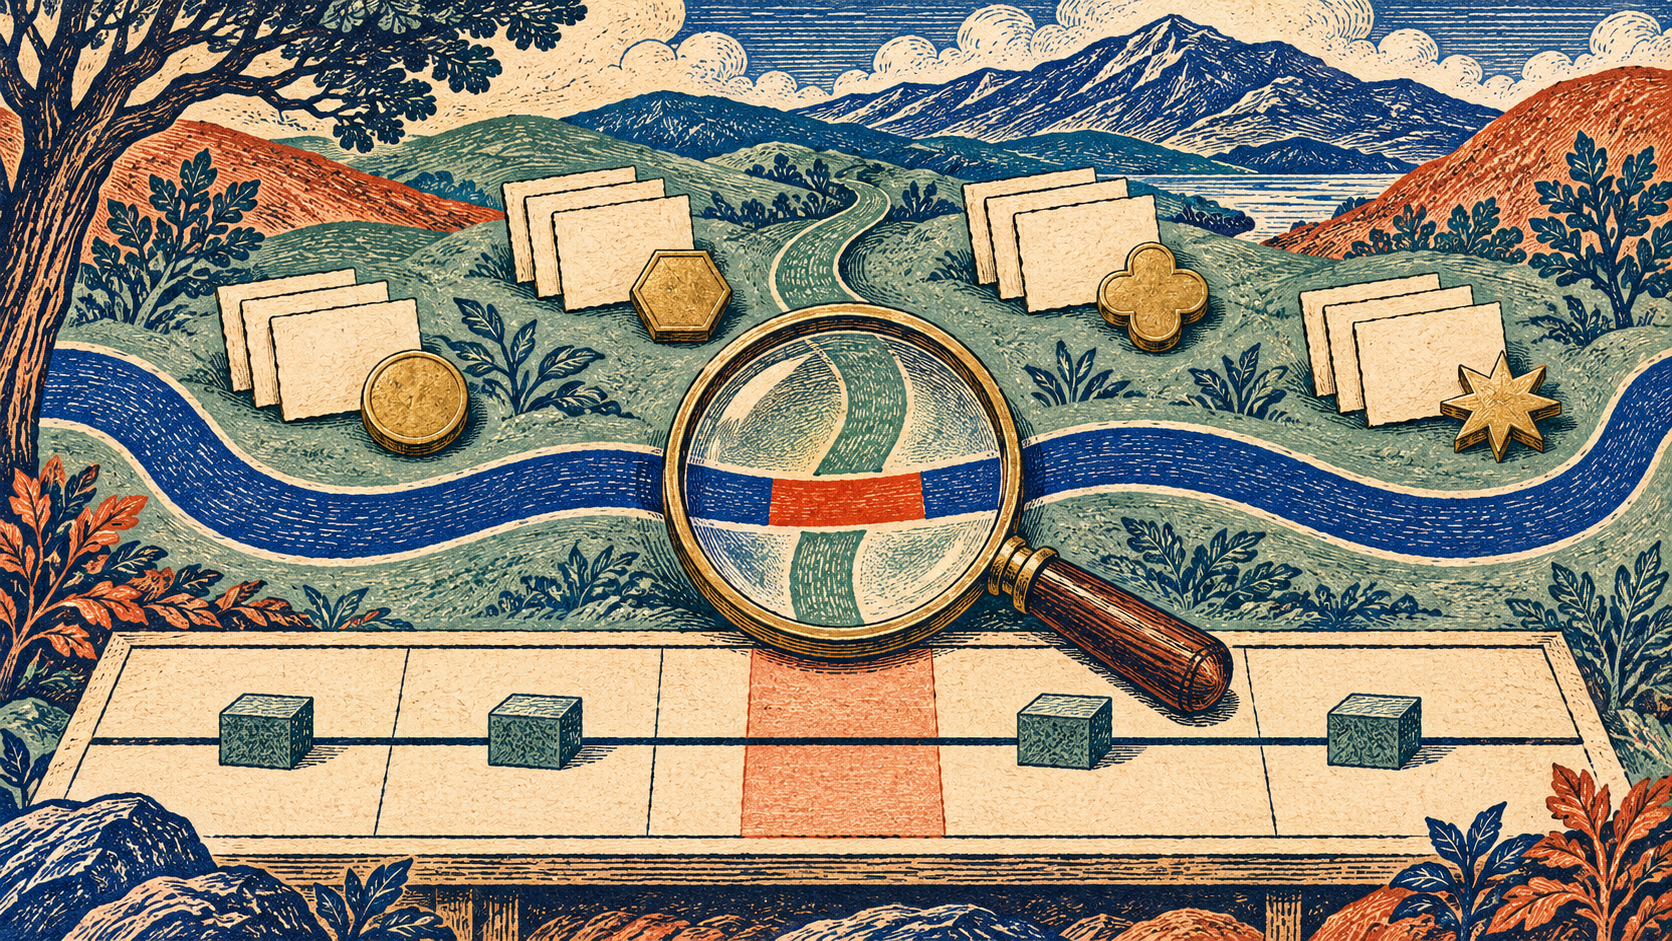
Use customer reports as case-level evidence in a separate post-incident impact review. Link each relevant report to the incident’s time window, affected customer task, product version or configuration, and a named symptom. Then compare that evidence with service metrics, account records, and incident timelines. Report the number of tickets separately from the estimate of affected customers, and label what the team knows, infers, and cannot yet measure.
A customer report count is the number of messages or cases received through a defined support channel during a stated period. It measures reporting activity. It does not by itself measure unique people affected, failed attempts, duration of harm, or the size of the customer population exposed. A post-incident review should keep those quantities separate so the team can explain what its evidence supports.
Start with the incident window and customer task
A review should establish what customers experienced, when the experience began and ended, and which product tasks were disrupted. The ticket count belongs in that account, but it is only one signal. Atlassian’s postmortem template lists the number of affected customers and the number of support tickets as separate impact details. Its incident-response guide also asks teams to record when impact started, what customers saw, how many customers were affected, and how many support cases they opened. Atlassian’s postmortem handbook and incident-response process make that distinction concrete.
Create one incident window with agreed timestamps and time zones. Record the first known customer impact, first internal detection, first support report, mitigation start, recovery, and any lingering effects. A customer may report an event well after it happened, so keep the occurrence time separate from the time the report arrived. Google’s SRE postmortem example recommends a detailed timeline with links back to supporting sources, while Atlassian’s handbook asks teams to capture impact, response, recovery, and timeline as separate fields. Google’s postmortem practices describe source-linked evidence; Atlassian’s handbook provides a practical timeline structure.
Build an evidence record for each relevant report
For every ticket that may relate to the incident, record a compact set of comparable fields:
| Field | What the reviewer records |
|---|---|
| Customer task | The action the customer tried to complete, such as exporting an invoice or accepting an invitation |
| Observed symptom | The customer’s words or a faithful summary of what happened |
| Occurrence time | When the customer says the failure occurred, with timezone or an uncertainty marker |
| Product context | Relevant release, browser, plan, region, configuration, or account role, when available and necessary |
| Evidence link | The original report, permitted attachment, support conversation, request ID, or telemetry reference |
| Confidence | Confirmed incident match, plausible match, unrelated, or unresolved |
| Next use | Impact estimate, timeline, communication review, or follow-up action |
This record keeps two questions distinct: “Did this case match the incident?” and “How many customers were affected?” One customer may file several cases for repeated failures. Several people in one organization may report different symptoms. A quiet support inbox can also reflect low usage, a hard-to-find reporting route, or customers who worked around the problem. These are reasons to verify the denominator, not reasons to discard the customer’s account.
Reconcile case evidence with reach
Compare support cases with a source that estimates exposure, such as failed requests, affected account IDs, product usage, regional rollout, or task-completion telemetry. Pick the source that matches the customer task. An infrastructure uptime chart may show that servers responded while invoice exports returned empty files; a request-failure metric may show attempts but not whether a person was blocked or retried successfully.
For example, a hypothetical incident has nine support tickets, six unique customer organizations, and a telemetry query showing 430 failed export attempts. Those numbers describe different units. The nine tickets are reports, six organizations are known reporters, and 430 is a count of attempts. The incident review should not convert any one of them into “430 customers affected.” It should ask whether retries belong to the same users, how many accounts made those attempts, whether the failure occurred inside the agreed time window, and whether the export task ultimately succeeded.
Use a three-level impact statement:
- Confirmed: evidence directly ties a customer or task to the incident window and symptom.
- Estimated: a documented query or sampling method supports a broader reach estimate, with assumptions stated.
- Unknown: the available data cannot establish reach or customer outcome.
AWS recommends that post-incident analysis state customer impact, identify supporting data, and assign corrective actions. Google SRE likewise emphasizes linking metrics and conclusions to their source data. AWS Well-Architected, Perform post-incident analysis and Google’s postmortem practices support evidence-backed estimates instead of unsupported precision.
A concise impact statement can read: “Between 14:10 and 14:42 UTC, customers attempting invoice export received blank files. We confirmed six affected organizations from support reports and identified 430 failed export attempts in telemetry. We cannot determine how many attempts belonged to the same user or whether each customer completed the task later.” That statement preserves scale, evidence, and uncertainty without disguising an attempt count as a customer count.
Use reports to inspect the response, not assign blame
Customer reports help the review team examine when the organization understood the impact, how support answered, and which communication gaps prolonged customer effort. Compare the first report with detection and mitigation timestamps. Ask whether the support agent had a safe workaround, whether incident ownership was clear, whether the status update matched the affected tasks, and whether support knew when the mitigation reached the customer’s environment.
A report arriving before an alert may show that customer-facing detection lagged behind the failure. A sequence of tickets after mitigation may reveal that the technical recovery did not complete a customer’s original task. Those findings describe system and process gaps. They do not prove that a particular responder caused the incident. Google SRE and AWS both recommend blameless analysis that focuses on contributing conditions and corrective action rather than assigning fault to an individual. Google SRE’s postmortem guidance and AWS Well-Architected support that approach.
Avoid reconstructing the whole review from memory or copying every support conversation into the postmortem. Link to the relevant source, quote only the minimum context needed, and record who verified the interpretation. Keep personal information and customer-specific detail to what the analysis requires. If the incident involves security, data loss, or a regulated workflow, follow the organization’s restricted review and retention process.
Convert evidence gaps into owned actions
A finding should identify the gap, owner, and verifiable end state. “Improve support during outages” is too broad to close. A stronger action might be: “Add the invoice-export failure mode to the support incident checklist; the support lead will verify it during the next incident exercise.” Another might be: “Add an account-level export outcome metric; the data owner will confirm it distinguishes retries from unique accounts.”
Sort actions by where they reduce customer impact:
- Prevent: stop the failure from being introduced or reaching the affected cohort.
- Detect: identify the customer task failure sooner, including when infrastructure health remains normal.
- Mitigate: restore or preserve the task while the underlying cause is investigated.
- Communicate: help support name affected customers, safe next steps, and update ownership.
- Verify: confirm the customer task works after mitigation and after the permanent fix.
AWS’s post-incident analysis guidance, updated 6 December 2023, recommends reviewing customer-impacting events, identifying contributing factors, and assigning preventative actions. Atlassian recommends tracking each postmortem action in the backlog of the team that owns it. AWS Well-Architected and Atlassian’s postmortem process support turning findings into owned work.
For small product teams that collect issue reports by voice, website widget, email, and form, Mendaro’s shared customer issue tracker can keep original reports and customer conversations together while staff review likely-duplicate suggestions. As an AI issue tracker for product teams and their customers, it can preserve the support evidence used in an incident review. The team still has to link cases to an incident timeline and validate impact against its own telemetry; the product does not replace incident-command or observability systems.
A five-minute evidence check
Before approving the post-incident review, confirm:
- The incident window uses explicit timestamps and time zones.
- Support cases are counted separately from unique customers and technical attempts.
- Every included report has a stated match confidence and a link to its source.
- The impact estimate names its data source, unit, assumptions, and unknowns.
- Findings include customer-task impact and support or communication gaps.
- Corrective actions have an owner and a result someone can verify.
A post-incident review earns trust when readers can trace its customer-impact claims to evidence and see what the team will change. A ticket count can direct attention toward missing evidence; the review must combine customer reports with operational data before estimating reach or deciding what to fix.
Sources and further reading
- Google SRE: Postmortem Practices for Incident Management, checked 7 November 2026
- Atlassian: Incident Postmortems, checked 7 November 2026
- Atlassian: How We Respond to an Incident, checked 7 November 2026
- AWS Well-Architected: REL12-BP02 Perform post-incident analysis, updated 6 December 2023 and checked 7 November 2026
- Mendaro: AI issue tracker with voice, widget, email, form, and customer tickets, checked 7 November 2026